
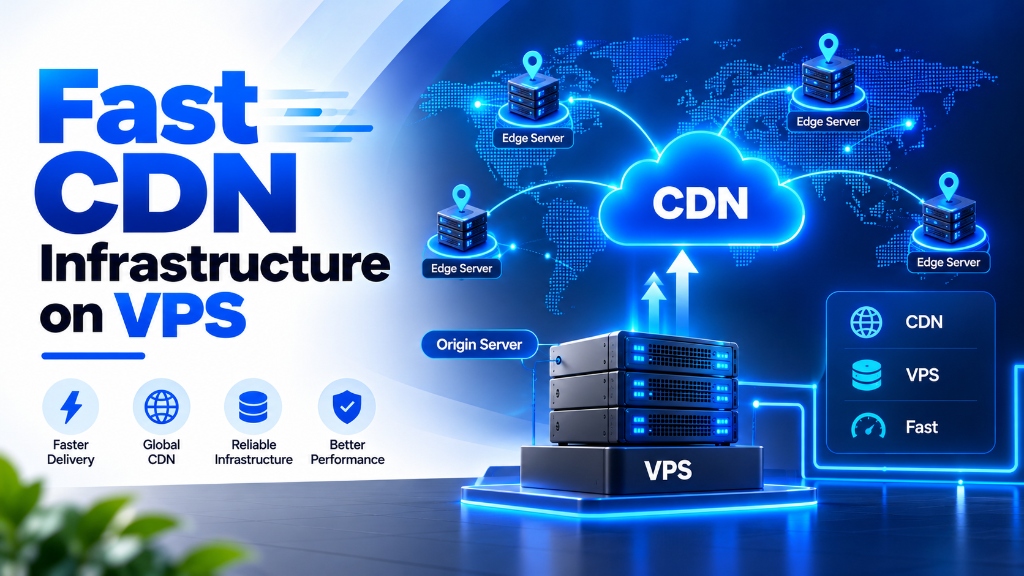
- The Edge Latency Fallacy: CDNs cache static media efficiently, but un-cacheable dynamic requests, authenticated sessions, carts, and REST APIs must travel all the way to the origin server.
- The TTFB Bottleneck: When an edge point of presence (POP) misses a cache request, visitor latency equals edge processing plus origin round-trip time, application rendering, and database execution.
- Full-Stack Origin Tuning: Slashing dynamic Time to First Byte (TTFB) requires kernel adjustments (TCP BBR, TCP Fast Open), persistent keepalive connections in Nginx, tuned PHP-FPM pools, and Redis in-memory caching.
- Strategic Infrastructure Placement: Deploying your backend stack on high-compute high-speed UK VPS solutions ensures low physical latency to local CDN edge hubs in London and Slough, guaranteeing consistent sub-100ms response times across UK networks.
1. The CDN Origin Dilemma: Why Edge Networks Fail on Dynamic Web Requests
Modern web architecture relies heavily on Content Delivery Networks to route traffic and serve content. By deploying distributed edge caches globally, services like Cloudflare, Fastly, CloudFront, and BunnyCDN deliver static assets within 10 to 25 milliseconds directly from local edge memory.
However, modern web platforms, SaaS dashboards, and online retail storefronts rely on customized user data. When a customer logs in, adds an item to their cart, submits a search filter, or executes a payment checkout, edge caches cannot return a static file. Instead, the edge point of presence (POP) generates an upstream cache miss, routing the request back to your origin server.
At that moment, the CDN becomes an additional proxy hop. The browser connects to the nearest edge node, which in turn establishes a connection to your origin server, waits for the web server to process the request, waits for runtime business logic, waits for database SQL queries, and streams the response back across the internet.
If your origin server takes 400 milliseconds to compile that response, the visitor experiences a TTFB exceeding 550 milliseconds regardless of edge proximity. Under Google’s Search Essentials and Core Web Vitals framework, a sluggish TTFB directly degrades Largest Contentful Paint (LCP) and Interaction to Next Paint (INP), harming search rankings and conversion rates.
2. Architectural Deep Dive: Anatomy of a Cache Miss and Connection Mechanics
When a visitor requests an uncached resource, two distinct network legs participate in the transaction: the front-leg (client-to-edge) and the back-leg (edge-to-origin). Optimizing the back-leg is where technical performance gains originate.
In an un-optimized setup, every edge node handling a cache miss negotiates a fresh TCP handshake followed by TLS cryptographic exchange with your origin server. Because global CDNs maintain dozens of edge facilities, your origin server faces thousands of concurrent transport handshakes every minute, consuming CPU cycles and adding network latency before application code executes.
To eliminate this latency, enterprise architectures implement HTTP persistent keepalive connections and Origin Shielding. Origin Shielding introduces an intermediate designated caching tier between global edge nodes and the origin. When regional edge nodes miss a resource, they query a centralized shield node located in London rather than overwhelming the origin directly. The shield node maintains warm, persistent connection pools directly to the origin server, eliminating recurring handshake penalties.
| Infrastructure Factor | Direct Un-Shielded CDN Origin | Optimized Origin with Shielding & Keepalive |
|---|---|---|
| TCP/TLS Handshake Frequency | High (Negotiated per edge proxy process) | Near-Zero (Persistent connection reuse) |
| Concurrent Socket Overhead | Thousands of TIME_WAIT sockets on origin | Consolidated pool of persistent HTTP/1.1 or H2 sockets |
| Cache Miss TTFB Variance | High (250ms to 800ms depending on distance) | Predictable, low variance (40ms to 95ms) |
| Traffic Surge Absorption | Vulnerable to origin socket exhaustion | Protected via shield request consolidation |
By structuring your network layer to maintain persistent upstream sockets, your server bypasses the overhead of cryptographic session resumption, preparing the Linux operating system kernel to handle intense ingress traffic without dropping packets.
3. Linux Kernel Tuning: Network Sockets, TCP BBR, and Buffer Allocation
Standard Linux distributions ship with default network configurations tuned for low-bandwidth environments. When functioning as a high-traffic CDN origin server, these default limits cause socket queue overflows, dropped SYN packets, and transmission delays under load. Tuning the kernel network stack via sysctl parameters provides an immediate boost to dynamic throughput.
The single most impactful kernel modification is enabling Google’s Bottleneck Bandwidth and RTT (BBR) congestion control algorithm. Traditional algorithms like CUBIC interpret packet loss as an indicator of network congestion, throttling transmission rates whenever a packet drops. In contrast, BBR continuously measures actual throughput and round-trip times, allowing your server to transmit data at maximum capacity even over slightly lossy consumer broadband networks.
Enabling TCP BBR and Expanding Connection Queues
Open your kernel configuration file and append the following parameters to /etc/sysctl.conf:
Apply these modifications dynamically without rebooting the server:
With BBR active and connection buffers expanded, your operating system will process incoming CDN socket handshakes instantly, preventing SYN flood false alarms and ensuring network packets flow smoothly.
4. Nginx Web Server Tuning: Keepalive Pools and FastCGI Microcaching
The reverse proxy web server functions as the primary front door for all incoming CDN requests. Implementing proper worker process allocation, socket keepalives, and memory-backed microcaching transforms Nginx into an enterprise-grade origin engine.
Configuring Nginx Core Worker Processes
In your main /etc/nginx/nginx.conf configuration, align worker processes directly with available CPU cores, and enable event multi-accept to distribute ingress load evenly across all processor cores:
Implementing FastCGI Microcaching for Semi-Dynamic Content
Many requests hitting your origin server are technically dynamic (such as category archives, recent blog posts, or product catalog listings) but remain valid for several seconds. By caching these generated HTML responses directly in shared system RAM (/dev/shm) for 1 to 10 seconds, your server handles traffic spikes effortlessly without invoking PHP execution cycles.
Define the microcache zone inside your Nginx HTTP block and apply it inside your domain’s server configuration:
This configuration allows anonymous visitors hitting cache misses to receive responses directly from shared memory in under 5 milliseconds, dramatically helping administrators speed up website performance with VPS hosting across dynamic publishing portals.
5. PHP-FPM Application Runtime Optimization: Static Pools and OPcache JIT
When dynamic requests genuinely require code execution (such as an authenticated member session or an e-commerce checkout), the application runtime becomes the primary determinant of TTFB. For PHP-based stacks like WordPress, Magento, Laravel, and Drupal, uncalibrated PHP-FPM pools lead to process queuing, where incoming HTTP requests stall waiting for an available execution worker.
Choosing Static Process Management
Switching to a static process pool keeps a fixed number of workers permanently resident in RAM, completely eliminating process-forking overhead. Edit your pool configuration (typically /etc/php/8.3/fpm/pool.d/www.conf) to tune worker capacity based on available memory:
Tuning Zend OPcache and JIT Compiler
Zend OPcache stores precompiled bytecodes in shared memory. In production, configure OPcache to never check file timestamps on disk, and activate the Just-In-Time (JIT) compiler:
These optimizations ensure that script execution finishes in tens of milliseconds rather than hundreds, allowing developers to optimize web performance with Linux VPS hosting even when handling complex database queries.
6. Database Optimization: In-Memory Object Caching with Redis
Behind every dynamic web request lies a database query. When a customer loads an account dashboard or searches products, your application executes dozens of SQL queries against MySQL or MariaDB. If the database reads tables from disk, query response times spike, directly inflating origin TTFB.
The solution involves a dual-layer strategy: configuring the InnoDB Buffer Pool properly and introducing a high-speed Redis in-memory object cache. Redis serves query results directly from system RAM in microseconds, bypassing SQL execution entirely.
Configuring MySQL/MariaDB InnoDB Memory Pools
The InnoDB Buffer Pool caches table data and indexes. Ensure that active working datasets remain in memory by updating /etc/mysql/my.cnf:
Deploying Redis via Low-Overhead Unix Sockets
Connecting to Redis via a local TCP loopback incurs kernel network overhead. Binding Redis to a Unix domain socket eliminates transport overhead and cuts latency by up to 25%:
Add the web user to the redis group and restart services:
7. Origin Security and Ingress Control: Restricting Traffic to CDN Subnets
An optimized origin server must also remain a protected server. If malicious scrapers, automated botnets, or volumetric DDoS attacks bypass your CDN and discover your origin server’s public IP address, they can overwhelm your compute cores, exhausting memory and causing widespread downtime.
True origin hardening requires enforcing strict ingress firewall rules so that only legitimate CDN edge proxies can establish HTTP and HTTPS connections. All direct public access to web ports 80 and 443 should be dropped at the firewall boundary.
Restricting Ingress Traffic to CDN Edge Subnets
Using Linux Uncomplicated Firewall (UFW), whitelist the published IP ranges of your CDN provider, while keeping administrative SSH ports secured via non-standard ports or private keys:
Additionally, implement Authenticated Origin Pulls (AOP) within Nginx to validate client certificates provided by the CDN, guaranteeing requests originate strictly from authorized CDN proxies.
8. Benchmarking and Verification: Measuring Edge-to-Origin TTFB Precision
Validating your optimization efforts requires precise telemetry that isolates origin performance from third-party edge caching. The industry standard tool for diagnosing server timing is curl, configured with custom output formatting to capture each distinct millisecond phase.
Capturing Granular Latency Metrics with cURL
Execute the following command directly against your origin server to record detailed connection timestamps:
Interpreting Real-World Diagnostic Results
In an un-tuned production stack, the Start Transfer (TTFB) metric often hovers between 0.450s and 0.850s. Following the kernel, Nginx, PHP-FPM, and Redis optimizations detailed in this guide, a tuned origin server consistently returns dynamic responses in 0.065s to 0.110s (65ms to 110ms), comfortably beating Google’s recommended 200ms threshold for top-tier page performance.
9. Troubleshooting Origin Bottlenecks and HTTP Gateway Errors
Even tuned servers occasionally encounter friction under heavy commercial load. Knowing how to diagnose upstream errors quickly ensures maximum uptime and customer trust.
1. Resolving HTTP 502 Bad Gateway
An HTTP 502 error indicates that Nginx received an invalid response from upstream application workers. The most common cause is an exhausted PHP-FPM worker pool. Inspect the error logs immediately:
If you observe server reached pm.max_children setting, increase pm.max_children in your PHP-FPM pool configuration if unallocated memory allows.
2. Resolving HTTP 504 Gateway Timeout
An HTTP 504 status indicates that upstream scripts took longer to complete than Nginx timeouts allow. Expand the timeout temporarily while investigating slow database queries:
10. Conclusion: Building a Resilient, High-Velocity Origin Foundation
A Content Delivery Network is only as effective as the origin infrastructure supporting it. While edge caching masks latency for static media, the core business transactions that drive revenue, registrations, and conversions rely entirely on how quickly your origin server processes and returns dynamic application data.
By systematically eliminating transport friction—enabling Linux TCP BBR congestion control, expanding socket backlogs, maintaining persistent Nginx upstream keepalive pools, enforcing static PHP-FPM worker allocations with OPcache JIT, and offloading queries to in-memory Redis sockets—you eliminate hundreds of milliseconds of dynamic delay. The result is an origin server capable of delivering instantaneous response times, acing Google Core Web Vitals, and providing an uncompromising digital experience for every visitor.
