

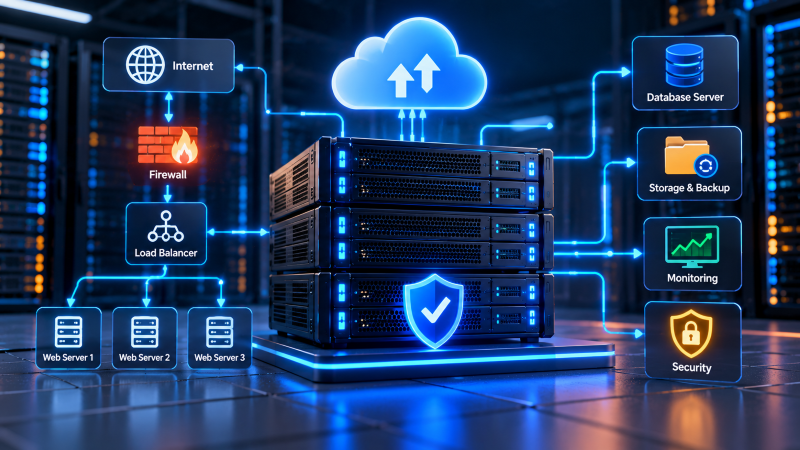
Quick Answer: Business Server Survival Hosting
Business server survival hosting is an infrastructure engineering discipline where virtual servers maintain continuous operation through hardware degradation, extreme traffic surges, and localized datacenter outages. Unlike commodity shared hosting, survival-grade hosting combines hardware-isolated KVM virtualization, dedicated high-frequency CPU cores, enterprise NVMe RAID-10 arrays, kernel-level socket tuning, and automated 3-2-1 offsite disaster recovery pipelines to deliver 99.99% operational availability and near-zero recovery objectives.
Modern digital enterprises operate in an unforgiving environment where unplanned downtime carries severe financial and reputational consequences. When a business-critical web application goes offline, live customer transactions abort, consumer trust degrades, paid marketing acquisition costs evaporate, and search visibility drops. While commodity hosting providers frequently advertise high availability as a passive marketing checkbox, true server survivability requires deliberate systems architecture, unshared hardware allocations, and proactive failure-mode planning.
When digital platforms encounter unexpected viral traffic spikes, volumetric network floods, or hypervisor memory contention, unhardened systems fail abruptly. Establishing an unyielding operational foundation requires selecting high-performance VPS hosting that pairs dedicated hardware allocations with deterministic storage throughput. For verified web server benchmarking and upstream socket parameters, engineers also rely on authoritative technical specifications from the official NGINX Documentation.
Four non-negotiable engineering requirements for maintaining continuous server uptime and transactional integrity under production stress:
Hardware Isolation Over Oversubscription
Shared hypervisors cause unpredictable CPU steal time; survival hosting mandates strict KVM virtualization with dedicated physical execution threads.
Storage Latency Dictates Throughput
Direct-attached NVMe arrays operating in hardware RAID-10 provide microsecond random I/O, preventing database deadlocks during traffic surges.
Kernel Network Stack Hardening
Default Linux sysctl limits drop packets prematurely; expanding socket queues and enabling Google BBR sustains line-speed transit under high concurrency.
Deterministic 3-2-1 Disaster Recovery
Automated hourly incremental snapshots with offsite encrypted replication guarantee aggressive Recovery Point (RPO) and Recovery Time Objectives (RTO).
Architectural Blueprint: Core Infrastructure Requirements for Server Survival
Surviving production stress requires that every server subsystem operate with built-in redundancy and predictable throughput. In production environments, catastrophic server crashes rarely stem from software bugs alone; they typically result from unmanaged physical bottlenecks that cascade across compute, storage, and networking layers until the entire operating system deadlocks.
A resilient business server infrastructure satisfies four fundamental technical requirements:
- Hypervisor-Level Compute Isolation: In shared hosting or containerized environments (such as OpenVZ or basic LXC), tenants share a single underlying operating system kernel. If a rogue tenant triggers a kernel panic or consumes excessive CPU cycles, all colocated applications degrade immediately. True survival architecture demands hardware-assisted Kernel-based Virtual Machine (KVM) virtualization, giving each instance discrete CPU scheduler slices and unshared memory allocations.
- Direct-Attached NVMe Gen4 Storage in RAID-10: Shared network-attached block storage introduces volatile latency spikes whenever multi-tenant storage networks saturate. Direct-attached PCIe Gen4 NVMe arrays organized in hardware RAID-10 provide sustained random 4K read/write speeds exceeding 80,000 IOPS while maintaining complete availability even if an individual drive experiences catastrophic physical failure.
- Multi-Homed Network Fabric with Anycast BGP: Relying on a single upstream internet transit carrier creates a catastrophic single point of failure. Resilient server facilities aggregate multiple Tier-1 transit providers governed by Border Gateway Protocol (BGP). If an international fiber link suffers a cut, BGP dynamically recalculates routing paths in milliseconds with zero dropped TCP connections.
- Autonomous Out-of-Band Management: When software configuration errors, corrupted firewall rules, or kernel deadlocks terminate SSH access, administrators must retain independent out-of-band management access. Virtual serial consoles and IPMI/VNC interfaces allow direct hardware-level access to repair boot sequences and resolve routing policies without requiring remote technician dispatches.
Compute, Memory & NVMe Sizing: Eliminating Resource Starvation Bottlenecks
A business server cannot withstand unexpected production stress if its underlying hardware resources are provisioned solely for average idle conditions. Capacity planning models peak concurrent sessions, memory allocation ceilings, and disk write amplification factors to eliminate starvation bottlenecks before they occur.
CPU Core Allocation and Hypervisor Scheduling
Virtual CPU cores (vCPUs) represent execution threads provisioned by the hypervisor. While clock frequency dictates how rapidly single-threaded transactional logic processes, core density governs total concurrent thread capacity. For dynamic application runtimes such as PHP-FPM, Python ASGI, or Node.js clusters, available compute capacity directly bounds active worker concurrency.
If a virtual server hosting a high-traffic e-commerce catalog is allocated only two virtual cores, sixty concurrent dynamic queries force the hypervisor scheduler into intense context-switching. This condition manifests as elevated CPU steal time (%st in top or vmstat). Survival-grade hosting guarantees dedicated high-frequency silicon (such as AMD EPYC or Intel Xeon Scalable processors) with sufficient core counts to maintain baseline processor utilization below 65% during peak trading hours.
Memory Overhead and the Linux Out-of-Memory (OOM) Killer
RAM is the single most critical hardware resource in server survival engineering. When an operating system exhausts physical memory, the Linux kernel invokes the Out-of-Memory (OOM) Killer. The kernel algorithm evaluates active processes via badness heuristics and forcibly terminates the largest memory consumer—which is almost invariably your relational database daemon (MySQL/MariaDB) or primary web server worker pool.
To protect mission-critical daemons from abrupt kernel termination, memory capacity must be mathematically allocated across four distinct operational zones:
- Base Operating System Reserve (15%): Dedicated to kernel memory mappings, network socket buffers, system logging, and essential management daemons.
- Database Buffer Pool (50%): Dedicated to
innodb_buffer_pool_size, ensuring all active database indexes and hot tables reside permanently in fast memory rather than disk storage. - Dynamic Application Worker Pool (25%): Reserved for dynamic PHP-FPM children or application runtimes based on measured per-process memory footprints.
- Surge Buffer & Page Cache (10%): Preserved to absorb unexpected traffic surges without forcing the kernel into aggressive disk swap paging.
| Workload Concurrency Profile | Recommended CPU Sizing | Minimum RAM Headroom | Storage Array Configuration | Target Concurrency Scale |
|---|---|---|---|---|
| Startup / Corporate Site | 2 Dedicated vCPUs (3.2+ GHz) | 4 GB ECC DDR4/DDR5 | 80 GB NVMe (RAID-1 Mirror) | Up to 15,000 Daily Unique Visits |
| Growing E-Commerce / SaaS | 4 to 8 Dedicated vCPUs | 16 GB to 32 GB ECC | 250 GB Enterprise NVMe (RAID-10) | 50,000 to 250,000 Daily Sessions |
| High-Volume Transaction Hub | 16+ Dedicated vCPUs / Bare Metal | 64 GB to 128 GB ECC | 1 TB+ Dual-Mirrored NVMe Pools | 500,000+ Daily Dynamic Requests |
| Disaster Recovery Replica Node | Matching Primary Production Specs | Equal to Primary Production Pool | Identical Read/Write IOPS Bandwidth | Instant Automated Failover |
Kernel-Level Optimization Runbook: sysctl & TCP Tuning for High Concurrency
Standard Linux distributions ship with conservative kernel default parameters designed for desktop computing or modest utility tasks. When an unhardened server encounters a sharp traffic surge, the operating system kernel silently drops incoming connection requests and exhausts file handles long before physical CPU or RAM capacities are reached.
To harden the operating system network stack against connection drops and socket exhaustion, apply these production directives to /etc/sysctl.d/99-business-survival.conf:
Apply these directives immediately into runtime memory without requiring a server reboot:
Activating Google BBR (Bottleneck Bandwidth and RTT) congestion control replaces legacy loss-based algorithms like Cubic. In high-traffic scenarios over long-distance WAN connections, transient packet jitter frequently causes Cubic to slash transmission rates by 50%. Google BBR continuously models real-time bandwidth and packet transit delay, delivering up to 35% higher network throughput and sub-100ms Time-to-First-Byte (TTFB) even under network congestion.
High Availability, Redundancy & Load Balancing Strategies
A resilient hosting infrastructure assumes that physical hardware components will inevitably experience failure. Designing for business server survival means ensuring that the unexpected degradation of any individual component never interrupts customer transactions or web accessibility.
In-Memory Caching and Database Offloading
Direct database disk reads represent the single most expensive operation in dynamic web hosting. Serving thousands of simultaneous user requests directly from disk storage creates I/O bottlenecks that paralyze worker processes. Deploying an in-memory caching layer using Redis dramatically reduces database contention:
- Query Caching: Frequently executed catalog queries, application configurations, and session tokens remain stored directly in volatile RAM, returning query results in sub-2 millisecond intervals.
- Transient Lock Management: Utilizing Redis as a distributed lock manager prevents multiple concurrent processes from executing duplicate database writes or triggering thread race conditions.
Web Server Concurrency Architecture
Deploying modern, event-driven web servers like NGINX or LiteSpeed Enterprise is essential for high-concurrency survival. Traditional process-per-connection architectures allocate an independent memory stack for every visitor, exhausting memory reserves under sudden traffic surges.
NGINX utilizes the asynchronous epoll() system call. A single master worker thread handles tens of thousands of simultaneous socket connections with minimal CPU clock switching and negligible memory overhead. Pairing NGINX with persistent upstream keepalive pools ensures backend PHP-FPM or Node.js workers remain connected, eliminating the latency of repeated TCP and TLS handshakes. For enterprise platforms requiring managed scaling, migrating to dedicated resources through reliable cloud hosting solutions provides predictable hypervisor boundaries and dedicated network bandwidth.
Automated Backup & Disaster Recovery: RPO, RTO and the 3-2-1 Architecture
Backups are meaningless if they cannot be restored under emergency conditions. True business survival requires establishing concrete recovery thresholds and continuously verifying restore integrity through automated test pipelines.
Understanding RPO and RTO
- Recovery Point Objective (RPO): The maximum tolerable age of data lost during an outage. An RPO of 1 hour means the business loses at most 60 minutes of transactional data.
- Recovery Time Objective (RTO): The maximum permissible elapsed time from an outage until systems are fully operational and serving traffic again.
The 3-2-1 Backup Strategy Implemented
- Three Total Copies of Data: Maintain primary live production data, an immediate on-server snapshot copy, and an external backup archive.
- Two Different Storage Media Types: Do not store primary backups on the same physical storage partition as your operating system. Utilize separate internal drive arrays or isolated Network Attached Storage (NAS) volumes to prevent local controller failures from compromising backups.
- One Copy Stored Offsite in a Distinct Location: The third copy must reside in a geographically distinct datacenter or enterprise object storage repository (such as an encrypted S3 bucket). If a regional outage strikes the primary datacenter, the offsite replica remains untouched and ready for deployment.
Automated Incremental Backup Verification
A backup that has never been tested is not a valid backup. Implement tools like BorgBackup or Restic combined with automated cron routines. These deduplicating backup engines compress and encrypt data (AES-256) at rest, transmitting only changed binary blocks across the network. Furthermore, schedule automated monthly restore tests into an isolated sandbox environment to verify database table integrity and script execution.
Enterprise Security Hardening & Zero-Downtime Defense
Automated botnets continuously probe public IP ranges searching for open ports, default credentials, and unpatched kernel vulnerabilities. A server cannot maintain uptime if malicious actors compromise root access or exhaust bandwidth through volumetric DDoS floods.
Stateful Firewall Configuration with UFW
By default, all inbound ports except essential public services must be locked down. A stateful firewall tracks network connection states, permitting return traffic for established outbound requests while dropping unauthorized connection attempts:
Cryptographic SSH Bastion Hardening
Password authentication represents a massive vulnerability for internet-connected servers. Automated brute-force scripts attempt thousands of credential combinations per minute, consuming processor cycles.
- Enforce Ed25519 elliptic-curve public-key authentication, which provides robust encryption while requiring fewer CPU cycles than traditional 4096-bit RSA keys.
- Disable password authentication entirely by configuring
PasswordAuthentication noin/etc/ssh/sshd_config. - Disable direct root logins (
PermitRootLogin no), requiring administrators to authenticate through an unprivileged user account before elevating credentials viasudo.
Automated Intrusion Defense via Fail2ban
Deploy Fail2ban to monitor authentication logs in real time. When an external IP address registers repeated failed authorization attempts against SSH, FTP, or login endpoints, Fail2ban dynamically updates firewall rules to block the offending IP address for 24 hours, neutralizing brute-force botnets at the kernel level.
Zero-Downtime Kernel Patching
Historically, applying critical Linux kernel security patches required scheduling maintenance windows and rebooting servers. Deploying live-patching technologies (such as Canonical Livepatch or Red Hat Kpatch) enables administrators to inject security updates directly into runtime kernel memory while the server remains live, eliminating maintenance downtime entirely.
Real-World Failure Scenarios and Recovery Strategies
To understand how survival hosting functions in production, consider these three failure modes and the architectural mechanisms that mitigate them:
Viral Traffic Spike and Concurrency Saturation
Traffic Surge Mitigation
An unexpected product launch or media mention drives 20x regular traffic. An unhardened server exhausts process limits, fills SYN backlogs, and drops connections with 504 Gateway Timeouts.
The event-driven NGINX reverse proxy handles incoming sockets asynchronously. The BBR congestion algorithm prevents TCP window throttling. Redis serves 85% of incoming catalog reads directly from RAM. Database queries remain within the pre-warmed buffer pool, keeping CPU utilization steady under 70%.
Catastrophic Solid-State Drive Degradation
Hardware Redundancy Failover
A primary solid-state drive suffers sudden controller failure during business hours. In single-drive hosting, the server crashes, corrupts databases, and requires hours of emergency hardware replacement.
The enterprise hardware RAID-10 storage controller detects the drive drop instantly. Read/write operations shift to mirrored drive extents in zero milliseconds without interrupting operating system I/O. A hardware alert dispatches datacenter technicians to hot-swap the degraded drive without powering down the host.
Accidental Table Deletion and Ransomware Recovery
Automated Snapshot Restore
A compromised administrator account or human error drops an essential transactional database table.
The hourly automated Restic backup pipeline maintains immutable, append-only encrypted snapshots in offsite object storage. Administrators spin up an on-demand staging instance, mount the snapshot from 45 minutes prior, verify table integrity, and restore operational state within an RTO of under 25 minutes.
Frequently Asked Questions
Deploy Unyielding Business Server Survival Hosting Today
Safeguard your commercial digital presence with hardware-isolated KVM virtualization, dedicated high-frequency CPU cores, enterprise NVMe RAID-10 storage pools, and unmetered Tier-1 fiber uplinks. Experience continuous uptime, sub-millisecond database queries, and 24/7 technical infrastructure engineering support designed to keep your business operating through any surge.
